

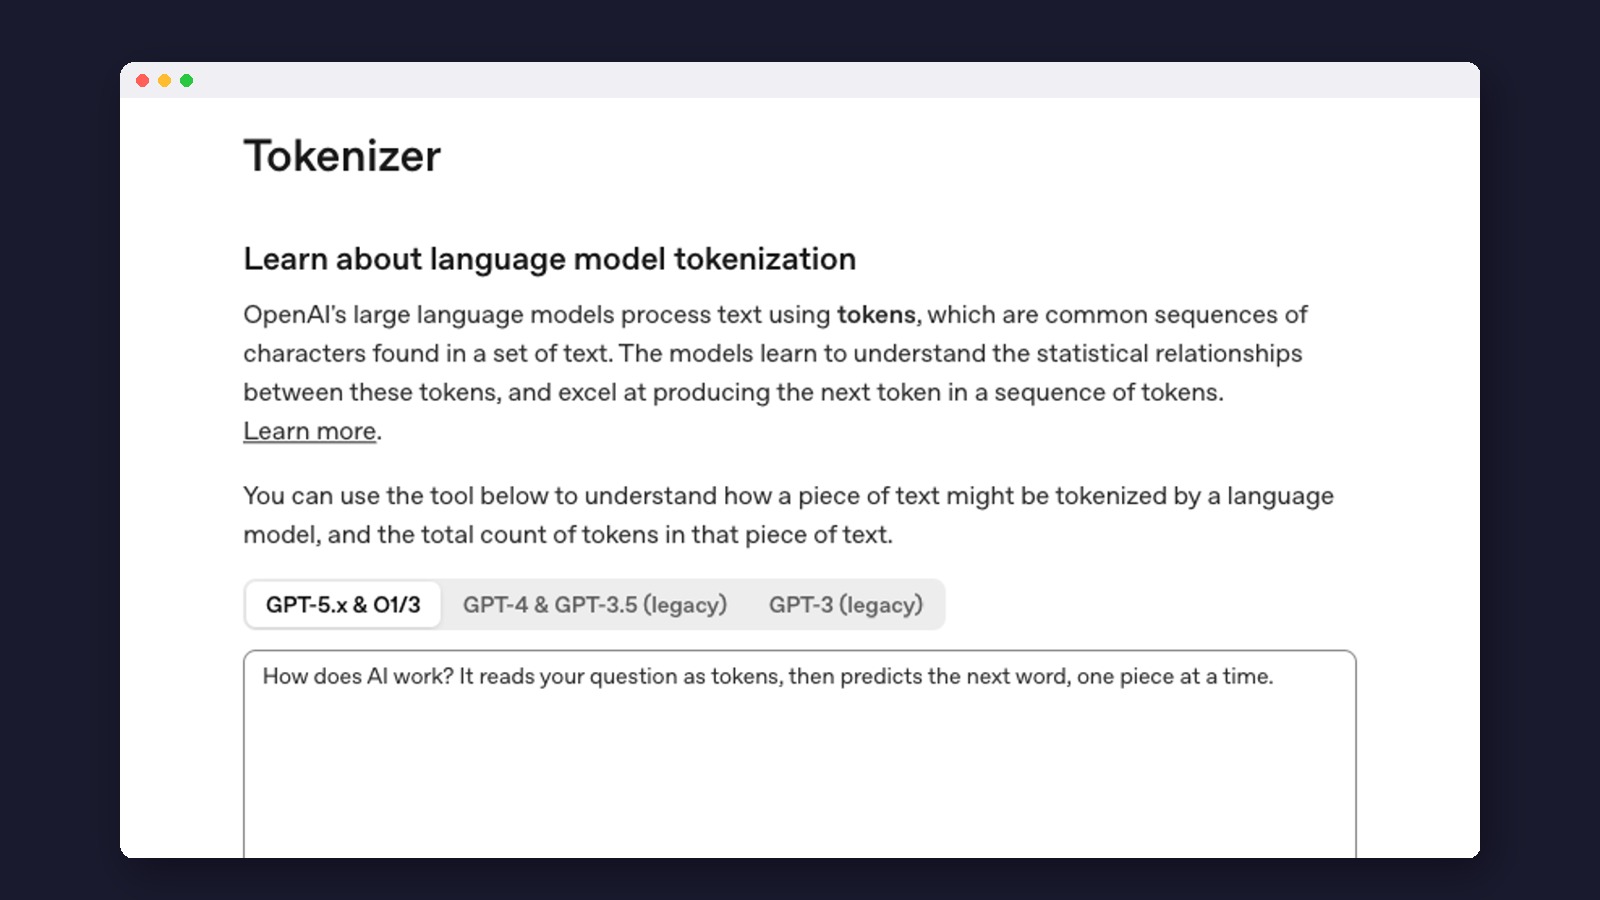
Updated November 2026 · We added a tokenizer screenshot and our own tests of whether ChatGPT, Claude and Gemini make things up
No math degree needed. This is what happens inside an AI when you type a question, explained with everyday comparisons and the real numbers behind it.
The short version: AI learns patterns from huge amounts of example data, then uses those patterns to predict: the next word in a sentence, what is in a photo, which email is spam. Chatbots like ChatGPT, Claude and Gemini write one small chunk of text at a time, choosing what is most likely to come next. Learning (training) is slow and costs millions; answering you (inference) takes seconds and keeps getting cheaper. Because the model predicts rather than looks things up, it can sound sure and still be wrong.
Artificial intelligence works by learning patterns from enormous amounts of data and then using those patterns to make predictions, generate text, recognize images, or make decisions. Think of it like this: when you were a child, nobody handed you a rulebook for identifying dogs. Instead, your parents pointed at hundreds of dogs and said “dog” until your brain figured out the common features: four legs, fur, snout, tail. AI learns the same way, except it processes millions of examples instead of hundreds, and it does it with math instead of neurons. Every AI system follows the same three-step cycle: it takes in data, finds patterns in that data, and then applies those patterns to new situations it has never seen before. The AI behind ChatGPT, Claude, and Gemini learned language by reading billions of web pages, books, and articles. The goal was not to memorize them but to learn the statistical relationships between words. When you ask ChatGPT a question, it is not searching a database for the answer. It is predicting, one word at a time, what word most likely comes next based on everything it learned during training. That is the basic mechanism behind how artificial intelligence works, and the sections below explain each piece in plain English.
Key Takeaways
- AI learns from data, not from programming rules. Engineers do not write instructions for every scenario. Instead, they feed the AI examples and let it discover patterns on its own.
- Training and inference are two separate phases. Training is the expensive, months-long learning process. Inference is the fast, cheap moment when the AI applies what it learned to your question.
- Neural networks are inspired by the brain but work differently. They use layers of math operations, not biological neurons, to transform inputs into outputs.
- Large language models predict the next word. ChatGPT, Claude, and Gemini generate responses by choosing the most probable next token, one at a time, thousands of times per answer.
- AI “hallucinations” happen because the model is guessing. When the model does not have strong patterns to rely on, it fills gaps with plausible-sounding but incorrect information.
- The three types of AI learning serve different purposes. Supervised learning uses labeled examples, unsupervised learning finds hidden structure, and reinforcement learning improves through trial and error.
How AI Processes Information: The Input-Pattern-Output Cycle
Every AI system, from a spam filter to a self-driving car, follows the same fundamental cycle: input, processing, output. The difference between a basic program and an AI system is what happens in the processing step. A traditional program follows rules written by a programmer (“if the email contains ‘Nigerian prince,’ mark it as spam”). An AI system learns its own rules by studying examples.
Here is a concrete analogy. Imagine you are training a new employee at a restaurant to identify which food orders are correct and which have errors. You could hand them a 500-page rulebook covering every possible mistake. Or you could sit with them for two weeks, showing them thousands of correct orders and thousands of incorrect ones, until they develop an intuition for spotting errors. AI takes the second approach: it learns by example instead of following a rulebook.
When an AI system processes information, it converts everything into numbers. Text becomes sequences of numerical tokens. Images become grids of pixel values. Audio becomes waveforms represented as numbers. The AI then passes these numbers through layers of mathematical operations, each layer extracting slightly more abstract features. In an image recognition system, the first layer might detect edges, the second layer combines edges into shapes, the third layer combines shapes into parts (like “ear” or “nose”), and the final layer combines parts into whole objects (“dog” or “cat”). Large modern networks stack dozens to hundreds of these layers.
How AI Training Works: Data, Patterns, and Predictions
Training an AI model is the process of adjusting millions (or billions) of numerical parameters until the model produces accurate results. The best analogy is tuning a massive mixing board in a recording studio. Each slider (parameter) controls a tiny aspect of the output. During training, the AI processes an example, compares its output to the correct answer, and then adjusts all its sliders slightly to reduce the error. Repeat this billions of times, and the sliders settle into positions that produce consistently accurate results.
The training process for a modern large language model follows several stages. First, engineers assemble a massive dataset. Meta says it trained Llama 3 on over 15 trillion tokens of publicly available text, roughly the words in 100 million books. OpenAI and other companies don’t publish these figures for their own models. This data includes web pages, books, academic papers, code repositories, and conversation transcripts. The model does not memorize this data. Instead, it learns the statistical relationships between words and concepts.
Next comes the pre-training phase. The model reads through the dataset, and for each sequence of text, it tries to predict what comes next. When it guesses wrong, the training algorithm calculates the error and adjusts the model’s parameters to make a better guess next time. How many parameters do today’s chatbots have? Nobody outside the companies knows. OpenAI’s GPT-4 technical report says it contains “no further details about the architecture (including model size)”, and Anthropic, OpenAI and Google don’t publish parameter counts for current models such as Claude Opus 5.5, GPT-6 or Gemini 4 Argon. Meta is an exception: its largest open model, Llama 3.1 405B, has 405 billion parameters and was trained on more than 16,000 Nvidia H100 chips. The bill is huge: asked whether GPT-4 cost $100 million to train, OpenAI’s Sam Altman said “It’s more than that” (Wired, 2023).
After pre-training, the model undergoes fine-tuning. This is where engineers narrow the model’s general knowledge into specific, useful behaviors. For conversational AI like ChatGPT, Claude, and Gemini, this involves Reinforcement Learning from Human Feedback (RLHF), where human evaluators rate the model’s responses and the model learns to produce responses that humans prefer. This stage is what transforms a raw text-prediction engine into a helpful assistant.
What is a neural network?
A neural network is the mathematical structure that powers most modern AI. Despite the name, it works very differently from your brain. Your brain has about 86 billion neurons, linked by an estimated 100 trillion or more connections, and it runs on roughly 20 watts (less than an old-style light bulb). An artificial neural network is a series of math equations organized in layers, running in data centers that draw millions of watts.
Here is the simplest possible explanation. A neural network takes numbers in, multiplies them by weights (the “parameters”), adds them up, applies a simple mathematical function, and passes the result to the next layer. That is it. The power comes from scale, not from any single operation. When you stack hundreds of layers, each with millions of parameters, the network develops the ability to represent extraordinarily complex patterns.
Think of it like a factory assembly line. Raw materials (your input data) enter at one end. At each station (layer), workers (mathematical operations) transform the materials slightly. By the time the product reaches the end of the line, it has been transformed from raw ingredients into a finished product (the AI’s output). Each station does very little; hundreds of them in a row produce the result.
There are a few main types of neural network, the building blocks of modern artificial intelligence. Convolutional Neural Networks (CNNs) excel at processing images by scanning small regions at a time, like reading a page by moving a magnifying glass across it. Recurrent Neural Networks (RNNs) process sequences by maintaining a “memory” of previous inputs, which suits data that arrives in order, like stock prices over time. And Transformer networks, introduced by Google researchers in 2017, process entire sequences simultaneously using a mechanism called “attention,” which lets the model weigh the importance of every word relative to every other word. Transformers are the architecture behind ChatGPT, Claude, Gemini and nearly every modern language model.
What is the difference between training and inference?
Understanding the difference between training and inference is essential for understanding how AI works and why it costs what it costs. Training is like going to school for 16 years. Inference is like using that education to do your job every day. Training happens once (or periodically, when the model is updated). Inference happens every time someone uses the AI.
Training is compute-intensive, time-consuming, and expensive. It requires thousands of specialized GPUs running for weeks or months. And the amount of computing keeps climbing: Epoch AI, which tracks these trends, says training compute for frontier language models has been growing about 5 times a year since 2020, and more than 30 models have now been trained at GPT-4’s scale or above. All of that runs in data centers. The International Energy Agency estimates that data centers used 485 terawatt-hours of electricity in 2025, with use by AI-focused data centers up 50% in one year, and expects the total to roughly double to 950 TWh by 2030, about 3% of the world’s electricity.
Data-center electricity use is expected to double by 2030
2024
2025
2030 (IEA projection)
Inference is comparatively cheap and fast. When you type a question into ChatGPT, the model is not learning anything new. It is running your input through its fixed, pre-trained parameters and generating an output. This takes seconds, not months. At scale it adds up: OpenAI says more than 1.2 billion people use ChatGPT each week. The good news is that the price keeps falling. Stanford’s AI Index found the cost of running a model as capable as GPT-3.5 dropped more than 280-fold between November 2022 and October 2024. Every word you send and receive still has a real computing cost behind it, which is why paid plans and usage limits exist.
One helpful analogy: training is like building a car factory (billions of dollars, takes years), while inference is like driving a car off the assembly line (relatively cheap per unit, takes minutes). The factory investment only makes sense if you are going to produce millions of cars. In the same way, training only pays off because billions of people use the resulting model.
How ChatGPT, Claude, and Gemini Generate Responses
Large language models like ChatGPT, Claude, and Gemini generate text through a process called autoregressive generation. In plain English: they predict one word (technically, one “token”) at a time, append it to the sequence, and then predict the next token based on everything that came before. They repeat this process hundreds or thousands of times until the response is complete.
Here is exactly what happens when you ask ChatGPT “What is the capital of France?”
- Your question gets converted into numerical tokens (in GPT-4’s tokenizer, “What” is token 3923 and “is” is token 374)
- These tokens pass through the model’s transformer layers (dozens of them, stacked one after another)
- The model scores every possible next token across its entire vocabulary (about 100,000 tokens for GPT-4, around 200,000 for newer OpenAI models) for what comes next
- It selects “The” as the highest-probability next token
- It appends “The” to the sequence and repeats steps 2-4
- It selects “capital” as the next token, then “of,” then “France,” then “is,” then “Paris”
- It continues generating tokens until it produces a stop signal
This process is why AI responses appear to stream in word by word: they are literally being generated one piece at a time. The model has no pre-written answers stored anywhere. Every response is generated fresh by this prediction process. This is also why the same question can produce slightly different answers each time: a parameter called “temperature” controls how much randomness is injected into the token selection process. Higher temperature means more creative but less predictable outputs. If you want to write better inputs for these models, our guide on how to write AI prompts covers the essentials.


Why does AI make things up?
AI hallucination is when a model generates information that sounds plausible and confident but is factually incorrect. This is not a bug in the usual sense; it comes straight from how these models work. Since the model generates text by predicting probable next tokens, it can produce sequences that are statistically likely but factually wrong.
The analogy here is a student who studied hard but is taking a test on material that was barely covered in class. They know enough about the subject to construct a convincing-sounding answer, but they are filling in gaps with educated guesses. Sometimes those guesses are right; sometimes they are plausible but wrong.
Hallucinations happen more frequently in several specific scenarios: when the model is asked about niche topics with limited training data, when asked for very specific numerical facts (dates, statistics, prices), when asked about events after its training cutoff date, and when asked to cite specific sources (it will often generate plausible-looking but non-existent URLs or paper titles). How often? It depends on the subject. A Stanford RegLab and HAI study of legal questions found hallucination rates from 58% to 88% when models were asked specific questions about real federal court cases. Newer models do better, but the lesson holds: the more specific and obscure the question, the more you should check.
Model developers combat hallucinations through several strategies: larger and higher-quality training datasets, RLHF fine-tuning that penalizes confident incorrect answers, Retrieval-Augmented Generation (RAG) that connects the model to external databases for fact-checking, and constitutional AI, a method Anthropic uses for Claude and described in a 2022 paper, which trains models to admit uncertainty rather than guess.
We tried to get three chatbots to make things up
On November 2, 2026, we gave ChatGPT (Instant, in a temporary chat), Claude (Haiku 5.5, in an incognito chat) and Gemini (the free Flash-Lite model, signed out) two traps.
Trap one: a book that doesn’t exist. We asked each for a summary of “the 2019 novel The Lantern Ledger by Odessa Varnum”, a title and author we invented, then confirmed nobody had used.

None of them took the bait. All three ran a web search, found nothing and said so. When we asked again and told them not to search, ChatGPT and Claude answered from memory and still declined to invent a plot. Gemini declined too, but its reply cited a web page, so it searched anyway. A made-up title with no trace online was easy for all three to catch.
Trap two: references from memory. This one tripped up two of the three. We asked: “From memory, without searching the web: list 3 peer-reviewed studies showing that office plants improve productivity. Give the authors, year, title and journal for each.” Then we checked all nine references on Crossref, the database publishers use to register papers.

| Assistant | References fully correct | What was made up |
|---|---|---|
| ChatGPT | 3 of 3 | None. Names, titles, journals and years all matched. |
| Gemini | 1 of 3 | Invented a subtitle and gave a co-author the wrong first name (Gretchen instead of Georgia). |
| Claude | 1 of 3 | Got two co-authors’ names wrong (Pearson-Mills for Pearson-Mims, plus wrong initials) and gave a 2008 paper a title it never had. It warned up front to check every reference. |
Because the papers are real, the wrong details are hard to spot. Gemini and Claude filled the gaps with details that sounded right, just like the student guessing on a test earlier on this page. Before you rely on a reference, search for its title yourself, or ask the chatbot to search the web and link the source.
How does AI get better over time?
AI models improve through a combination of better training data, larger scale, architectural innovations, and improved fine-tuning techniques. GPT-2 (2019) had 1.5 billion parameters and GPT-3 (2020) had 175 billion. OpenAI stopped publishing the number with GPT-4 in 2023; leaked estimates put it around 1.8 trillion, but OpenAI has never confirmed that. Each generation represents not just more parameters but also better training techniques and data quality.
AI in numbers
But scaling alone is not enough. Several other factors drive improvement:
- Better training data curation. Early models were trained on whatever text was available online. Modern models use carefully filtered and deduplicated datasets, with toxic content removed and high-quality sources weighted more heavily.
- Architectural innovations. The shift from RNNs to Transformers in 2017 was a step change in capability. More recent design changes let models run faster and handle longer texts.
- Post-training alignment. RLHF, newer training methods, and constitutional AI methods have dramatically improved how models follow instructions and avoid harmful outputs.
- Inference-time compute. Newer techniques allow models to “think longer” on hard problems by using more compute at inference time (working through a problem step by step before answering), rather than relying solely on the patterns learned during training.
Key moments in how today’s AI got here
- 2016DeepMind’s AlphaGo beats Go champion Lee Sedol 4-1, using reinforcement learning.
- 2017Google researchers introduce the Transformer, the design behind nearly every chatbot today.
- 2019OpenAI’s GPT-2 has 1.5 billion parameters.
- 2020GPT-3 has 175 billion parameters, more than 100 times as many.
- 2022ChatGPT launches on November 30 and puts a language model in anyone’s hands.
- 2023GPT-4 arrives, and OpenAI stops publishing how big its models are.
- 2024Meta releases Llama 3.1 405B, an open model with 405 billion parameters.
- 2026More than 1.2 billion people use ChatGPT each week.
Individual deployed models do not learn from their conversations with you. When you chat with ChatGPT, your conversation does not update the model’s parameters. Learning happens during training runs, which occur periodically. Depending on your settings, companies may use conversations to train future versions (most let you opt out in privacy settings), but the model answering you today is a fixed snapshot.
The Three Types of AI Learning (In Plain English)
There are three main approaches to training AI, each suited to different types of problems. Here they are, stripped of jargon.
Supervised Learning: Learning from Labeled Examples
Supervised learning is the simplest to understand. You give the AI a dataset where every example has a correct answer attached. “Here is a photo of a cat, the label is ‘cat.’ Here is a photo of a dog, the label is ‘dog.’” The model studies thousands of these labeled examples and learns to predict labels for new, unseen data.
Human analogy: A teacher grading homework. The student (AI) submits answers, the teacher (labeled data) marks them right or wrong, and the student adjusts their understanding based on the feedback.
Real-world uses: Email spam detection, medical image diagnosis, credit card fraud detection, voice assistants recognizing speech.
Unsupervised Learning: Finding Hidden Patterns
Unsupervised learning gives the AI data without any labels and asks it to find structure on its own. The model looks for clusters, correlations, and anomalies that humans might miss.
Human analogy: Sorting a pile of unlabeled photographs into groups. Nobody tells you the categories; you naturally sort them into “beach photos,” “family dinners,” “work events” based on visual similarity.
Real-world uses: Customer segmentation in marketing, anomaly detection in cybersecurity, topic modeling in document analysis, recommendation engines (Netflix, Spotify).
Reinforcement Learning: Learning Through Trial and Error
Reinforcement learning trains an AI by letting it take actions in an environment and rewarding it for good outcomes while penalizing bad ones. The model learns a strategy (called a “policy”) that maximizes its cumulative reward over time.
Human analogy: Learning to ride a bicycle. Nobody gives you a textbook on physics and balance. You just try, fall, adjust, try again, and gradually develop the skill through experience. Every fall is a penalty signal; every smooth ride is a reward signal.
Real-world uses: Game-playing AI (DeepMind’s AlphaGo beat Lee Sedol, winner of 18 world titles, 4-1 in March 2016), robotics control, autonomous driving, and the RLHF process that makes ChatGPT and Claude helpful and safe. If you are exploring which AI tools to start with, our roundup of the best AI tools for beginners covers the most accessible options.
Visual Explanation: AI Concepts Mapped to Human Experience
The table below maps core AI concepts to familiar human experiences.
| AI Concept | Human Analogy | Real-World Example |
|---|---|---|
| Training data | Textbooks and life experience | Llama 3 was trained on over 15 trillion tokens of text |
| Parameters (weights) | The strength of memories and associations | Llama 3.1 405B has 405 billion parameters |
| Neural network layers | Levels of understanding (letters to words to sentences to meaning) | Large models stack dozens of transformer layers |
| Training | Studying for an exam: reviewing wrong answers and adjusting | Llama 3.1 405B trained on more than 16,000 GPUs; frontier runs cost tens to hundreds of millions of dollars |
| Inference | Taking the exam: using what you already know | ChatGPT answers in seconds (longer when it “thinks”) using fixed parameters |
| Overfitting | Memorizing the textbook word-for-word instead of understanding concepts | A model that aces its practice data but stumbles on new data |
| Hallucination | Confidently giving a wrong answer on an exam by guessing | ChatGPT citing a research paper that does not exist |
| Fine-tuning (RLHF) | An internship after college, adapting general knowledge to a specific job | Anthropic uses Constitutional AI + RLHF to align Claude |
| Temperature (sampling) | Choosing between “safe” and “creative” answers | Low temp = precise answers; high temp = creative writing |
| Token | A syllable or word chunk, the smallest unit of reading | In GPT-4’s tokenizer, “Unbelievable” is 3 tokens: “Un” + “belie” + “vable” |
Frequently Asked Questions
Can AI think like a human?
No. Current AI systems, including the most advanced large language models, do not think, understand, or experience consciousness. They are sophisticated pattern-matching systems that process numerical representations of data through mathematical operations. When ChatGPT produces a response that seems thoughtful, it is generating statistically probable sequences of tokens, not reasoning through a problem the way a human does. The AI field distinguishes between Artificial Narrow Intelligence (ANI), which excels at specific tasks, and Artificial General Intelligence (AGI), which would match human-level reasoning across all domains. Most researchers would say every AI system available in 2026 is still ANI. The question of whether AGI is achievable, and whether it would constitute “thinking”, remains one of the most debated topics in computer science and philosophy.
How does ChatGPT know what to say?
ChatGPT does not “know” anything in the way humans know things. It predicts the most likely next token in a sequence based on patterns learned from its training data. When you ask it a factual question, the correct answer happens to be the most statistically probable completion given that particular input. This is why it is generally accurate on well-documented topics (where the training data contains many consistent examples) but less reliable on obscure or recent topics (where the statistical signal is weaker). Its responses are also shaped by its RLHF fine-tuning, which trained it to produce responses that human evaluators rated as helpful and harmless.
Does AI understand what it’s saying?
This is one of the most debated questions in AI research, and the short answer is: we do not know for certain, but most experts lean toward “no” for current systems. AI models can produce outputs that appear to show understanding: they can explain concepts, draw analogies, and even pass professional exams. But these behaviors can be explained by sophisticated pattern matching without requiring real comprehension. The philosopher John Searle’s “Chinese Room” thought experiment (1980) illustrates this distinction: a person who follows rules to produce correct Chinese responses does not understand Chinese, even though their output is indistinguishable from a native speaker’s. Current AI may be doing something similar: producing correct outputs through pattern matching without true understanding.
How much data does AI need to learn?
It depends enormously on the task. A simple classifier (spam vs. not spam) might perform well with tens of thousands of labeled examples. A large language model requires trillions of tokens. Meta’s Llama 3 was trained on more than 15 trillion tokens; OpenAI, Anthropic and Google don’t publish their figures. For comparison, an online encyclopedia with millions of articles holds only a few billion words, so these models train on thousands of times more text. However, the trend in AI research is moving toward achieving more capability with less data. Few-shot learning techniques allow models to perform new tasks with just a handful of examples, and synthetic data generation allows models to create their own training data for specialized domains.
Will AI ever become conscious?
Nobody knows, and anyone who claims certainty in either direction is overstating what current science can tell us. Consciousness remains one of the hardest unsolved problems in science. We do not even have a universally accepted definition of what consciousness is, let alone a reliable test for it. Current AI systems show no credible evidence of consciousness, subjective experience, or sentience. They do not have desires, emotions, or awareness of their own existence. The question of whether sufficiently advanced computation could give rise to consciousness is fundamentally a philosophical question, not an engineering one. Most mainstream AI researchers, including leaders at OpenAI, Anthropic, and DeepMind, believe that current architectures are very unlikely to produce consciousness regardless of scale, but acknowledge that our understanding of consciousness is too limited to make absolute claims about future systems.
What This Means for You
Understanding how AI works is more than academic curiosity. It is becoming a practical life skill. When you understand that AI generates text by predicting probable tokens, you become a better judge of when to trust its output and when to verify. When you understand that training data shapes behavior, you can anticipate a model’s limitations. And when you understand the difference between training and inference, you can have informed opinions about the real costs, energy implications, and future trajectory of the technology.
The gap between people who understand AI and people who do not is growing. You do not need to become a machine learning engineer. But understanding the basics (AI learns from data, recognizes patterns and makes predictions) puts you in a far better position to use these tools effectively, evaluate claims about AI capabilities critically, and take part in decisions about how it gets used.
For a wider overview of the field, our guide to what artificial intelligence is covers the foundational concepts. And if you want to stay current as the technology evolves, our daily newsletter breaks down the latest developments in plain English.
Sources
- OpenAI: GPT-4 technical report (2023)
- Wired: Sam Altman on GPT-4’s training cost (2023)
- Meta: Introducing Llama 3
- Meta: Llama 3.1 405B
- Epoch AI: trends in AI training
- Epoch AI: models trained above 10^25 FLOP
- IEA: Key Questions on Energy and AI (April 2026)
- Stanford HAI: AI Index 2025
- OpenAI: GPT-6 for everyone (October 2026)
- Stanford HAI: legal hallucinations study (2024)
- Vaswani et al.: Attention Is All You Need (2017)
- Anthropic: Constitutional AI (2022)
- Google DeepMind: AlphaGo
- Azevedo et al.: neuron count in the human brain (2009)
- Balasubramanian: brain power (PNAS, 2021)
- Anthropic: models overview
- OpenAI: models
- Google: Gemini models
You May Also Like
- AI Tokens Explained
- Machine Learning vs Deep Learning
- What Is Training Data?
- What Is Inference?
- The Transformer Paper That Changed AI
- The Complete History of AI
- How to Use AI: A Step-by-Step Guide
- Best Free AI Courses for Beginners
- AI Tools Directory
Made for regular people, by a real person
How AI works, explained simply, plus the tools worth trying this week. One free email a day. Curated and edited by a human, in plain English.
Free forever. Unsubscribe anytime.